2 Matrix Product Vectors
Fix a physical dimension \(d\) and a bond dimension \(D\). All tensors here are translation-invariant with periodic boundary conditions (PBC).
2.1 Basic definitions
A (translation-invariant, PBC) MPS tensor with physical dimension \(d\) and bond dimension \(D\) is a collection of matrices \(\{ A^i\} _{i=0}^{d-1}\), where \(A^i \in M_{D}(\mathbb {C})\), indexed by a physical index \(i \in \{ 0, \ldots , d{-}1\} \). Such a tensor defines an MPV family. Diagrammatically,

The black node denotes the tensor \(A\), the horizontal legs are virtual, and the upper leg is the physical index \(i\).
Given a word \(w = (i_1, \ldots , i_L) \in \{ 0,\ldots ,d{-}1\} ^L\), the word evaluation is the matrix product
The empty word evaluates to the identity, \(A^\varnothing = \mathbb {1}_D\). In tensor-network notation,
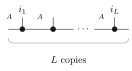
in which each black node denotes the same local tensor \(A\), the virtual legs remain open, and the physical legs are labelled by the word \((i_1,\ldots ,i_L)\).
For a configuration \(\sigma =(\sigma _0,\ldots ,\sigma _{N-1})\), let \(w_\sigma =[\sigma _0,\ldots ,\sigma _{N-1}]\). Then \(A^{w_\sigma } =A^{\sigma _0}A^{\sigma _1}\cdots A^{\sigma _{N-1}}\).
This follows by induction on \(N\) from the recursive definition of word evaluation.
For any words \(w_1, w_2\), \(A^{w_1 \cdot w_2} = A^{w_1} A^{w_2}\).
The claim follows from the definition of \(A^w\).
If a matrix \(Z \in M_{D}(\mathbb {C})\) commutes with every element of \(M_{D}(\mathbb {C})\), then there exists \(\lambda \in \mathbb {C}\) such that \(Z = \lambda \mathbb {1}_D\).
Since \(Z\) commutes with every matrix unit, all off-diagonal entries of \(Z\) vanish and all diagonal entries are equal.
Let \((A_i)_{i\in I}\) span \(M_{D}(\mathbb {C})\), and let \(C:\mathbb {C}^{m_2}\otimes \mathbb {C}^D\longrightarrow \mathbb {C}^{m_1}\otimes \mathbb {C}^D\) satisfy, for every \(i\in I\),
Then there is a matrix \(F:\mathbb {C}^{m_2}\to \mathbb {C}^{m_1}\) such that \(C=F\otimes \mathbb {1}_D\).
Each \((a,b)\) multiplicity block of \(C\) commutes with every \(A_i\). Since the \(A_i\) span the full matrix algebra, Lemma 2.1.5 makes this block a scalar multiple of the identity. These scalars are the entries of \(F\).
The matrix product vector (MPV) of a tensor \(A\) at system size \(N\) is the vector
Equivalently, for a configuration \(\sigma = (i_1, \ldots , i_N) \in \{ 0,\ldots ,d{-}1\} ^N\), we write
The coefficient function \(\sigma \mapsto V^{(N)}(A)_\sigma \) gives the components of the vector in (2); the displayed ket is the corresponding vector in \((\mathbb {C}^d)^{\otimes N}\). For a general word \(w\), we also write \(c_w(A) := \operatorname{tr}(A^w)\). The MPV family generated by \(A\) is the collection \(\mathcal{V}(A) = \bigl\{ |V^{(N)}(A)\rangle \bigr\} _{N \ge 1}\). The coefficient \(V^{(N)}(A)_\sigma \) is the periodic contraction
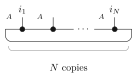
of \(N\) copies of the local tensor \(A\), with the outer virtual legs closed by the trace.
2.2 Transfer maps and quantum-channel interfaces
Transfer maps connect matrix product states to completely positive maps and quantum channels. The underlying channel theory is developed in the companion volume [ 216 , “Positive map” and “Quantum channel” ] .
The transfer map associated to a tensor \(A\) is the linear map \(\mathcal{E}_A : M_{D}(\mathbb {C}) \to M_{D}(\mathbb {C})\) defined by
Diagrammatically, the transfer map is the double-layer contraction

in which the upper node denotes \(A\), the lower node denotes \(A^\dagger \), and the physical index is summed over between them.
The transfer map is automatically positive: if \(X \ge 0\) then \(\mathcal{E}_A(X) \ge 0\), because each summand \(A^i X (A^i)^\dagger \) is positive semidefinite. The abstract framework is developed in the companion quantum-channel volume [ 216 , “Positive map” ] .
The transfer map \(\mathcal{E}_A(X)=\sum _i A^iX(A^i)^\dagger \) is completely positive.
It is already written in the Kraus form (established in the companion quantum-channel volume [ 216 , “Completely positive map” ] ), with Kraus operators \(\{ A^i\} \).
For an MPS tensor \(A=\{ A^i\} _{i=0}^{d-1}\), the matrix representing \(\mathcal{E}_A\) under vectorization is
Apply the standard vectorization identity \(\operatorname {vec}(AXB)=(B^{\mathsf T}\otimes A)\operatorname {vec}(X)\) to each summand \(A^iX(A^i)^\dagger \) and sum over the physical index.
For an MPS tensor \(A\) and bond matrices \(\sigma , \rho \in M_{D}(\mathbb {C})\),
where \(\mathcal{E}_{A^\dagger }\) is the transfer map with Kraus operators \((A^i)^\dagger \).
Apply trace adjointness for Kraus maps [ 216 , “Trace adjointness of a Kraus map” ] to the Kraus family \(\{ A^i\} \).
Let \(A\) be an MPS tensor and let \(w\in \mathbb {C}\). Then, for every bond matrix \(X\),
Expand the transfer map and pull the scalar \(w\) and its conjugate out of each summand.
If \(A\) is left canonical, then, for every bond matrix \(X\),
Cyclicity of trace gives
since left canonicity makes the sum in parentheses equal to the identity.
If \(\sum _i(A^i)^\dagger A^i=\mathbb {1}\), then the transfer map \(\mathcal{E}_A(X)=\sum _i A^iX(A^i)^\dagger \) is a quantum channel (CPTP).
Complete positivity is Theorem 2.2.3. Trace preservation follows by cyclicity and the normalization hypothesis:
Let \(A{\gt}0\) be a square complex matrix and let \(V\) be a possibly rectangular matrix satisfying \(VV^\dagger =\mathbb {1}\). Then
For a row vector \(x\), one has
Moreover, \(xV=0\) implies
Thus every nonzero \(x\) gives \(xV\ne 0\), and positive definiteness of \(A\) makes the displayed quadratic form strictly positive.
2.3 Site-periodic tensor families
For a fixed period \(m\), a site-periodic tensor family is a family of local tensors indexed by \(\{ 0,\ldots ,m{-}1\} \), with local physical dimension \(d\) and bond dimension \(D\).
For site-periodic tensors \(A,B\) at fixed period \(m\):
equality of the induced site-periodic states;
cyclic gauge equivalence.
Both periodic relations are equivalence relations (reflexive, symmetric, transitive).
2.4 Gauge equivalence and same MPV
Two tensors \(A\) and \(B\) of the same bond dimension \(D\) are gauge equivalent if there exists an invertible matrix \(X \in \mathrm{GL}_D(\mathbb {C})\) such that, for every \(i \in \{ 0,\ldots ,d{-}1\} \),
In tensor-network notation, (8) is represented by

where the black node denotes the tensor \(A\), the upper leg is the physical index \(i\), and the two red side nodes denote the gauge matrices acting on the virtual legs.
Two tensors \(A\) and \(B\) (of the same bond dimension) generate the same MPV family if \(|V^{(N)}(A)\rangle = |V^{(N)}(B)\rangle \) for every system size \(N\).
For tensors \(A\) and \(B\) of possibly different bond dimensions \(D_1\) and \(D_2\), we write \(\mathcal{V}(A) = \mathcal{V}(B)\) if \(|V^{(N)}(A)\rangle = |V^{(N)}(B)\rangle \) for every word length \(N\), including the empty word. This algebraic relation is used for exact direct-sum identities.
For tensors \(A\) and \(B\) of possibly different bond dimensions, we write \(\mathcal{V}^+(A) = \mathcal{V}^+(B)\) if \(|V^{(N)}(A)\rangle = |V^{(N)}(B)\rangle \) for every \(N {\gt} 0\).
Let \(A\) and \(B\) have the same physical alphabet and respective bond dimensions \(D_A\) and \(D_B\). A reduction from \(B\) to \(A\) is a pair \(V\in \mathbb {C}^{D_A\times D_B}\) and \(W\in \mathbb {C}^{D_B\times D_A}\) such that
for every word \(\mathbf a\), including the empty word. This is the reduction of [ 221 , Proposition 20 and the following definition ] .
The forward statements are the two defining clauses. For the converse, \(A^{\varnothing }=1_{D_A}\) and \(B^{\varnothing }=1_{D_B}\), so the empty-word instance reads \(V1_{D_B}W=1_{D_A}\). Since \(V\) has a right inverse, it is surjective, and finite-dimensional linear algebra gives \(D_A\leq D_B\).
Two tensors \(A\) and \(B\) (of possibly different bond dimensions) generate nonzero proportional MPV families if for every \(N{\gt}0\) there is a nonzero scalar \(c_N \in \mathbb {C}\) such that \(|V^{(N)}(A)\rangle = c_N |V^{(N)}(B)\rangle \). This is the projective reading of the proportionality hypothesis in [ 13 , Theorem 2.10 ] .
Two tensors \(A\) and \(B\) are eventually nonzero proportional if, for all sufficiently large \(N\), there is a nonzero scalar \(c_N \in \mathbb {C}\) such that \(|V^{(N)}(A)\rangle = c_N |V^{(N)}(B)\rangle \). This auxiliary form is used with the eventual linear-independence statement Lemma E.1.7.
Nonzero proportionality implies eventual nonzero proportionality, is symmetric, and equality of MPV families is the special case with scalar \(1\), at every positive length.
The eventual form follows by viewing an all-length statement as an eventual one. Symmetry follows by inverting the scalar \(c_N\) at each length, and equality is the case \(c_N = 1\).
Let \(R\) be a ring, let \(V\) be an \(R\)-module, and let \(I\) and \(K\) be finite index sets. Let \(T\subseteq I\), and let \(\{ u_i\} _{i\in I}\) and \(\{ v_k\} _{k\in K}\) be vectors in \(V\). Suppose that, for every \(i\notin T\), there are a scalar \(\alpha _i\) and an index \(\phi (i)\in K\) such that \(u_i=\alpha _i v_{\phi (i)}\). If
and the coproduct-indexed family \(w\colon T\amalg K\to V\), defined by \(w(\operatorname {inl}(i))=u_i\) and \(w(\operatorname {inr}(k))=v_k\), is linearly independent, then \(a_i=0\) for every \(i\in T\).
Substitute \(u_i=\alpha _i v_{\phi (i)}\) for \(i\notin T\) and collect the resulting coefficients over the fibres of \(\phi \). The given equality is then a linear relation in the combined family. Linear independence makes every coefficient vanish, in particular each \(a_i\) with \(i\in T\).
Let \(\zeta A\) denote the tensor with matrices \(\{ \zeta A^i\} _{i=0}^{d-1}\). Then, for any word \(w\), \((\zeta A)^w = \zeta ^{|w|} A^w\), where \(|w|\) is the length of \(w\).
Induction on \(w\): the base case gives \(\zeta ^0 = 1\), and each step picks up one factor of \(\zeta \).
Let \(\zeta A\) denote the tensor with matrices \(\{ \zeta A^i\} _{i=0}^{d-1}\). Then, for every \(N\) and every configuration \(\sigma = (i_1, \ldots , i_N)\), \(V^{(N)}(\zeta A)_\sigma = \zeta ^{N} V^{(N)}(A)_\sigma \).
Apply Lemma 2.4.12 to the word \(w = (i_1, \ldots , i_N)\) of length \(N\), then take the trace; the scalar \(\zeta ^{N}\) pulls out by linearity.
Two tensors \(A\) and \(B\) are gauge-phase equivalent if there exist \(X \in \mathrm{GL}_D(\mathbb {C})\) and \(\zeta \in \mathbb {C}\setminus \{ 0\} \) such that, for every physical index \(i\),
Gauge equivalence is the special case \(\zeta = 1\).
Two tensors are unit gauge-phase equivalent when the gauge-phase equation holds with \(|\zeta |=1\).
Unit gauge-phase equivalence implies gauge-phase equivalence.
A unit-modulus scalar is nonzero.
Gauge-phase equivalence is symmetric after identifying equal bond dimensions. Moreover, suppose that \(A\), \(B\), and \(C\) have identified bond dimensions, that \(X_1\) and \(X_2\) are invertible, that \(\zeta _1,\zeta _2\ne 0\), and that, for every physical index \(i\),
Then
so \(B\) and \(C\) are gauge-phase equivalent after the corresponding identification of their bond dimensions.
Symmetry follows by replacing \((X,\zeta )\) with \((X^{-1},\zeta ^{-1})\). Formula (12) follows by substituting the first gauge formula into the second.
If \(B^i = X A^i X^{-1}\) for all \(i\), then \(B^w = X A^w X^{-1}\) for every word \(w\).
Induction on the word length, using \(X X^{-1} = \mathbb {1}\).
If \(A\) and \(B\) are gauge equivalent, then they generate the same MPV family.
Let \(B^i = X A^i X^{-1}\). By Lemma 2.4.18, \(B^w = X A^w X^{-1}\) for every word \(w\). Then \(\operatorname{tr}(B^w) = \operatorname{tr}(X A^w X^{-1}) = \operatorname{tr}(A^w)\) by cyclicity of the trace.
If \(B^i = \zeta X A^i X^{-1}\) for every physical index \(i\), then for every system size \(N\) and configuration \(\sigma \) one has \(V^{(N)}(B)_\sigma = \zeta ^N V^{(N)}(A)_\sigma \).
Combine gauge covariance of word evaluation with scalar scaling, then take traces.
2.5 Injectivity and normality
A tensor \(A\) is injective if its matrices span the full matrix algebra: \(\operatorname{span}_{\mathbb {C}}\{ A^i : i = 0,\ldots ,d{-}1\} = M_{D}(\mathbb {C})\).
If \(A\) is an injective MPS tensor, then its transfer map \(\mathcal{E}_A\) is irreducible.
If \(P\) is an invariant projection for \(\mathcal{E}_A\), then \((\mathbb {1}-P)A^iP=0\) for all \(i\). Since the \(\{ A^i\} \) span \(M_{D}(\mathbb {C})\), \((\mathbb {1}-P)MP=0\) for all \(M\), so \(P=0\) or \(P=\mathbb {1}\).
The inverse-tensor characterization of injectivity says that \(A\) is injective exactly when there is a tensor \(A^{-1}\) such that
Thus (13) identifies the two pairs of virtual indices when \(A^{-1}\) is contracted with \(A\) through their common physical index. In shorthand, \(A^{-1}A=\mathbb {1}\). This is the identity used in [ 13 , Section 2.3, lines 324–331 ] .
A tensor \(A\) is \(L\)-block injective if
An injective tensor is \(1\)-block injective.
If the one-site matrices \(\{ A^i\} _{i=0}^{d-1}\) span \(M_{D}(\mathbb {C})\), then the length-one word products span \(M_{D}(\mathbb {C})\), so \(A\) is \(1\)-block injective.
The length-one words are exactly the letters \(i \in \{ 0,\ldots ,d{-}1\} \), and evaluating a length-one word gives the matrix \(A^i\). Thus the length-one word span is the same span as in one-site injectivity.
A tensor \(A\) is normal [ 17 ] if there exists a positive integer \(L_0\) such that \(A\) is \(L_0\)-block injective.
If \(A\) and \(B\) are gauge equivalent and \(A\) is \(L\)-block injective, then \(B\) is \(L\)-block injective.
Conjugation by an invertible matrix maps the span of the length-\(L\) words of \(A\) onto the span of the length-\(L\) words of \(B\). Since conjugation is an automorphism of the full matrix algebra, fullness of the first span implies fullness of the second.
If \(A\) and \(B\) are gauge equivalent and \(A\) is normal, then \(B\) is normal.
Apply Lemma 2.5.6 at a blocking length for which \(A\) is block-injective.
The algebraic characterization of normality in Definition 2.5.5 (eventual block injectivity) is equivalent to the spectral characterization of [ 17 , Definition IV.1 ] (primitivity of the trace-preserving normalized transfer map \(\mathcal{E}_A\)); see [ 233 , Proposition 3 ] . In this development, the equivalence is established by Lemma 6.7.2.1, Theorem 6.7.4.4, Theorem 6.8.2, and Theorem 7.9.2.1.
2.6 Canonical form
Here, a block-injective canonical form for a tensor consists of:
a number of blocks \(r \ge 1\),
bond dimensions \(D_1, \ldots , D_r\),
injective tensors \(\{ A_k^i\} _{i=0}^{d-1}\) with \(A_k^i \in M_{D_k}(\mathbb {C})\) for each block \(k \in \{ 1,\ldots ,r\} \),
scaling factors \(\mu _1, \ldots , \mu _r \in \mathbb {C}\).
The associated tensor is the block-diagonal tensor
This block-injective formulation of the canonical form is used in [ 228 ] ; see also [ 17 ] for the normal canonical form.
For a finite direct sum \(\bigoplus _k \mathbb {C}^{D_k}\), the block projection \(P_j\) is the matrix that is the identity on the \(j\)-th summand and zero on all other summands.
A matrix on \(\bigoplus _k \mathbb {C}^{D_k}\) is block diagonal if it is a direct sum of square matrices, one on each summand.
A matrix on \(\bigoplus _k \mathbb {C}^{D_k}\) is block diagonal if and only if every entry from one summand to a distinct summand is zero.
The forward direction follows from the definition of a direct sum of matrices. Conversely, if all off-block entries vanish, the diagonal blocks reconstruct the original matrix.
If a matrix on \(\bigoplus _k \mathbb {C}^{D_k}\) commutes with every block projection \(P_j\), then it is block diagonal.
Compare the \((i,j)\) block of the identity \(XP_j=P_jX\) for \(i\ne j\). The right multiplication by \(P_j\) keeps that block, while the left multiplication by \(P_j\) kills it. Hence every off-block entry is zero, and Lemma 2.6.5 applies.
Given \(r\) blocks with bond dimensions \((D_k)_{k=1}^r\), per-block tensors \(\{ A_k^i\} \), and scaling factors \((\mu _k)_{k=1}^r\), the associated block-diagonal tensor is the tensor of total bond dimension \(D = \sum _{k=1}^r D_k\) defined by
For a word \(w\), the word evaluation of a block-diagonal tensor remains block diagonal:
Induct on the word and multiply block-diagonal matrices block by block; every letter contributes one scalar factor \(\mu _k\) on the \(k\)-th block.
The MPV of a block-diagonal tensor decomposes as
Equivalently, for each configuration \(\sigma \) one has
By Lemma 2.6.8, the full word evaluation is block diagonal with blocks \(\mu _k^N A_k^w\) for a word \(w\) of length \(N\). Taking the trace of a block-diagonal matrix gives the sum of the block traces: \(\operatorname{tr}(A^w) = \sum _k \mu _k^N \operatorname{tr}(A_k^w)\).
2.7 Blocking
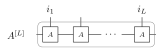
Given a tensor \(A\) and a blocking length \(L\), the \(L\)-blocked tensor is the tensor with physical index set \(\{ 0,\ldots ,d{-}1\} ^L\) (hence physical dimension \(d^L\)) and the same bond dimension \(D\), whose matrices are indexed by words \((i_1, \ldots , i_L) \in \{ 0,\ldots ,d{-}1\} ^L\):
Blocking coarse-grains \(L\) neighbouring sites into one tensor: the inner virtual bonds are contracted, the \(L\) physical legs merge into a single composite index, and the two outer bonds remain as the bond of \(A^{[L]}\).
If \(w = (J_1, \ldots , J_m)\) is a word in the blocked alphabet, where each \(J_k\) is an \(L\)-tuple in \(\{ 0, \ldots , d{-}1\} ^L\), then concatenating the block words gives a word \(\widetilde{w}\) of length \(mL\) in the original alphabet and \((A^{[L]})^w = A^{\widetilde{w}}\).
Induct on the blocked word \(w\) and split off the first block word. Lemma 2.1.4 turns concatenation of blocks into multiplication of the corresponding evaluations.
For each basis state \(\sigma = (\sigma _1, \ldots , \sigma _N)\) of the blocked system, where each \(\sigma _k\) is an \(L\)-tuple in \(\{ 0, \ldots , d{-}1\} ^L\), there exists a basis state \(\widetilde{\sigma } = (\widetilde{\sigma }_1, \ldots , \widetilde{\sigma }_{NL})\) of the original system such that \(V^{(N)}(A^{[L]})_\sigma = V^{(NL)}(A)_{\widetilde{\sigma }}\).
Concatenate the block words and apply the blocked word evaluation lemma (Lemma 2.7.2).
If \(A\) and \(B\) generate the same MPV family, then for any blocking length \(L\), the blocked tensors \(A^{[L]}\) and \(B^{[L]}\) also generate the same MPV family.
By Lemma 2.7.3, each MPV coefficient of the blocked tensor \(A^{[L]}\) equals a coefficient of \(A\) at the corresponding concatenated configuration. The same holds for \(B^{[L]}\) (with the same concatenated configuration). Since \(A\) and \(B\) agree on all configurations, so do \(A^{[L]}\) and \(B^{[L]}\).
2.8 MPV overlap
We regard \(|V^{(N)}(A)\rangle \) as an element of \(\mathbb {C}^{d^N}\) indexed by configurations \(\sigma \in \{ 0,\ldots ,d{-}1\} ^N\), with \(\sigma \)-component \(V^{(N)}(A)_\sigma \) as in Definition 2.1.7. This allows us to use the standard Euclidean inner product on \(\mathbb {C}^{d^N}\).
The MPV inner product between two tensors \(A\) and \(B\) at system size \(N\) is
i.e. the Euclidean inner product on \(\mathbb {C}^{d^N}\) (conjugate-linear in the first argument).
The MPV overlap between two tensors \(A\) (of bond dimension \(D_1\)) and \(B\) (of bond dimension \(D_2\)) at system size \(N\) is
Diagrammatically, the overlap contracts the MPV ring of \(A\) against the conjugate ring of \(B\) along their shared physical indices, both virtual rings closed by the trace:
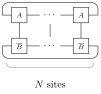
This pairing is linear in the first MPV coefficient and conjugate-linear in the second. By Lemma 2.8.4, it is the complex conjugate of the Hilbert-space inner product from Definition 2.8.2.
\(O_{AB}(N) = \overline{\langle V^{(N)}(A) | V^{(N)}(B) \rangle }\).
The overlap sums \(V_\sigma \overline{W_\sigma }\) while the inner product sums \(\overline{V_\sigma } W_\sigma \). Complex conjugation swaps these.
If \(V^{(N)}(A)_\sigma = V^{(N)}(A')_\sigma \) and \(V^{(N)}(B)_\sigma = V^{(N)}(B')_\sigma \) for all \(N {\gt} 0\) and all \(\sigma \), then \(O_{AB}(N) = O_{A'B'}(N)\) for all positive \(N\).
Direct pointwise rewriting: if the MPV coefficients agree for all positive chain lengths, the overlap sums are identical.